
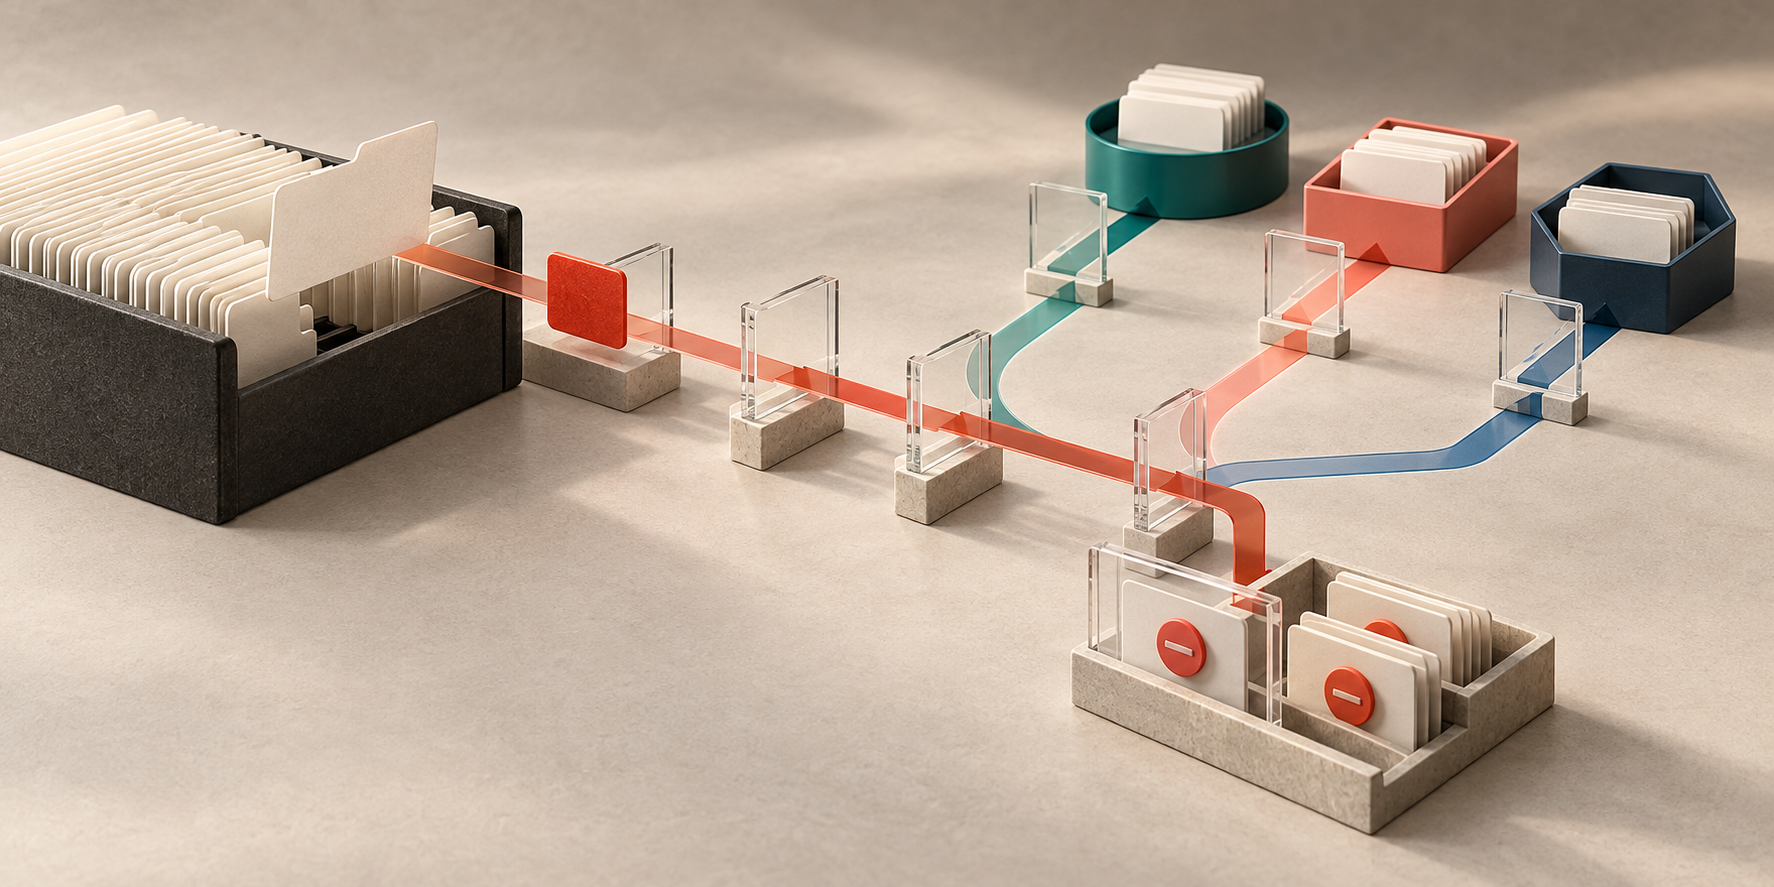
Deleting a record in one system does not make it disappear everywhere. A contact can be removed from a CRM while an email platform still considers the person subscribed, an analytics warehouse still counts the record, and a local integration table still sends it downstream. The visible deletion is small. The data workflow behind it is not.
That is why deletion should be treated as a data event with a defined meaning, an identifier, an owner, and a validation path. The goal is not to erase every trace immediately. The goal is to make every connected system respond deliberately and consistently.
Start by defining what “deleted” means
Teams often use one word for several different actions:
- Archived: The record is no longer active, but it remains available for history or audit.
- Suppressed: A person or address must not receive a particular type of communication.
- Deactivated: The record is retained, but it cannot participate in current workflows.
- Merged: Two records become one, so references to the old identity need to resolve to the surviving record.
- Hard-deleted: The source removes the record and may no longer be able to return its attributes.
These states have different downstream consequences. An archived customer may still belong in historical revenue reporting. A suppressed contact may need to remain in a global do-not-send list. A merged constituent may require a redirect from an old ID to a surviving ID. A hard deletion may require irreversible removal of personal fields while retaining a minimal audit event.
Before building a sync, write the state model down. Name the source of truth, the allowed transitions, the fields that must be removed, the fields that may be retained, and the systems that must receive the change.
Use a stable identity for the deletion event
A deletion event should identify the record that changed without depending on an email address, display name, or other mutable field. Those values can be shared, corrected, or removed before the event reaches another system.
Prefer a stable source ID plus an event ID or version. A useful event may contain:
- The source system and record type
- The stable record ID
- The state transition, such as active to archived or active to deleted
- The event ID and source version
- The event timestamp and processing timestamp
- The reason or policy code, where appropriate
- The retention class and permitted downstream actions
Do not put unnecessary personal data into a deletion message. If a destination can locate a record by stable ID, the event does not need to carry the full profile. This reduces exposure and prevents stale attributes from being copied into logs, queues, or retry tables.
Separate source deletion from downstream action
A source record changing state does not tell every destination exactly what to do. The CRM may need to mark a person inactive. The email platform may need to suppress future sends. The analytics pipeline may need to preserve an aggregate but remove event-level attributes. A reporting database may need a tombstone so later imports do not recreate the record.
Make those decisions explicit in a destination action matrix:
| Destination | Possible action | Validation |
|---|---|---|
| CRM | Archive, merge, or mark inactive | Source ID resolves to the intended record and state |
| Email platform | Suppress, unsubscribe, or remove from a segment | Future send eligibility reflects the new state |
| Analytics | Restrict, delete, or aggregate personal event data | Historical reporting follows the retention policy |
| Warehouse | Apply a tombstone or update the dimension state | Later loads do not re-create the active record |
This table is not a vendor feature list. It is an implementation contract. It gives engineering, marketing, analytics, and compliance teams one place to review what the same state transition means in each system.
Choose tombstones, retention, or erasure deliberately
When a source no longer returns a record, a normal incremental sync may interpret the absence as “nothing changed.” That is how stale copies survive. A deletion-aware workflow needs a way to communicate that the record existed and is no longer active.
A tombstone is a small durable marker that says a source identity was deleted, merged, or deactivated. It can include the source ID, state, event version, and retention deadline without retaining the original profile. Downstream imports can check tombstones before creating records from old exports or late-arriving events.
Retention rules still matter. Some systems need a limited audit trail; others require personal fields to be removed quickly. Document which fields are retained, for how long, and why. A deletion workflow that removes the source row but leaves full copies in logs, backups, spreadsheets, or error queues has not completed its job.
Protect against late events and stale re-creation
Deletion creates a race between old data and new state. A delayed update, a retry from before the deletion, or a backfill from an old export can try to restore the record.
Use version or freshness checks where the source provides them. An older update should not overwrite a newer deletion state. If events do not have usable versions, record the deletion timestamp and apply a conservative policy: late data may be quarantined for review instead of automatically recreating the record.
Also consider merge events. If record A is merged into record B, deleting A is not the same as deleting the person. The downstream workflow may need to redirect relationships, update foreign keys, and prevent future events for A from creating a new standalone record.
Make retries safe without hiding failures
Deletion events need retry behavior just like create and update events. A timeout after a destination accepts the change creates an unknown outcome. Retrying blindly can produce duplicate audit entries, re-run a destructive action, or obscure the original failure.
Give each logical state change a stable event identity. Store the destination operation status separately from the source state. A useful status model distinguishes:
- Received and validated
- Applied successfully
- Already applied, so the retry is safe to acknowledge
- Rejected because the destination record is missing or ambiguous
- Blocked because the action requires review
- Unknown and awaiting reconciliation
For destructive actions, idempotency is not a substitute for authorization. Confirm that the event is allowed to perform the destination action, that the target record matches the stable identity, and that the operation is logged without exposing sensitive values.
Validate the whole path
A unit test that changes a source record is not enough. Test the workflow from the original state through every destination and recovery path.
- Create a clearly labeled test record in a non-production environment.
- Confirm its source ID and current state in every destination.
- Apply an archive, suppression, merge, or deletion transition.
- Verify the emitted event contains the expected identity and state.
- Confirm each destination performs the documented action.
- Replay the same event and verify that the result remains safe and consistent.
- Deliver an older update after the deletion and confirm it cannot silently recreate the record.
- Inspect logs, retry tables, exports, and reporting outputs for unintended personal data.
Then test operational recovery. What happens when the CRM is unavailable? When the email platform returns a validation error? When the warehouse receives the tombstone before the profile update? A good workflow leaves a reviewable record of what happened and gives the team a bounded way to reconcile it.
Put ownership around the state model
Deletion handling crosses organizational boundaries. Marketing may own send eligibility. Engineering may own the event pipeline. Analytics may own historical reporting. Operations or compliance may define retention requirements.
Assign an owner for the state model, the destination action matrix, and the reconciliation queue. Review the model when a platform, field, identifier, or retention rule changes. Without ownership, a deletion workflow slowly becomes a collection of assumptions that each system interprets differently.
Conclusion
Deleted records do not stop being part of a connected data system the moment one application removes them. The deletion itself is information: it tells downstream systems how to stop using an identity, preserve the right history, prevent stale re-creation, and prove that the change reached its destinations.
DigitalWerks can review a deletion, merge, or suppression workflow across your website, CRM, email platform, analytics, and data integrations. We can help define the state model, map destination actions, protect stable identities, and build the validation and reconciliation checks that make data changes trustworthy.