
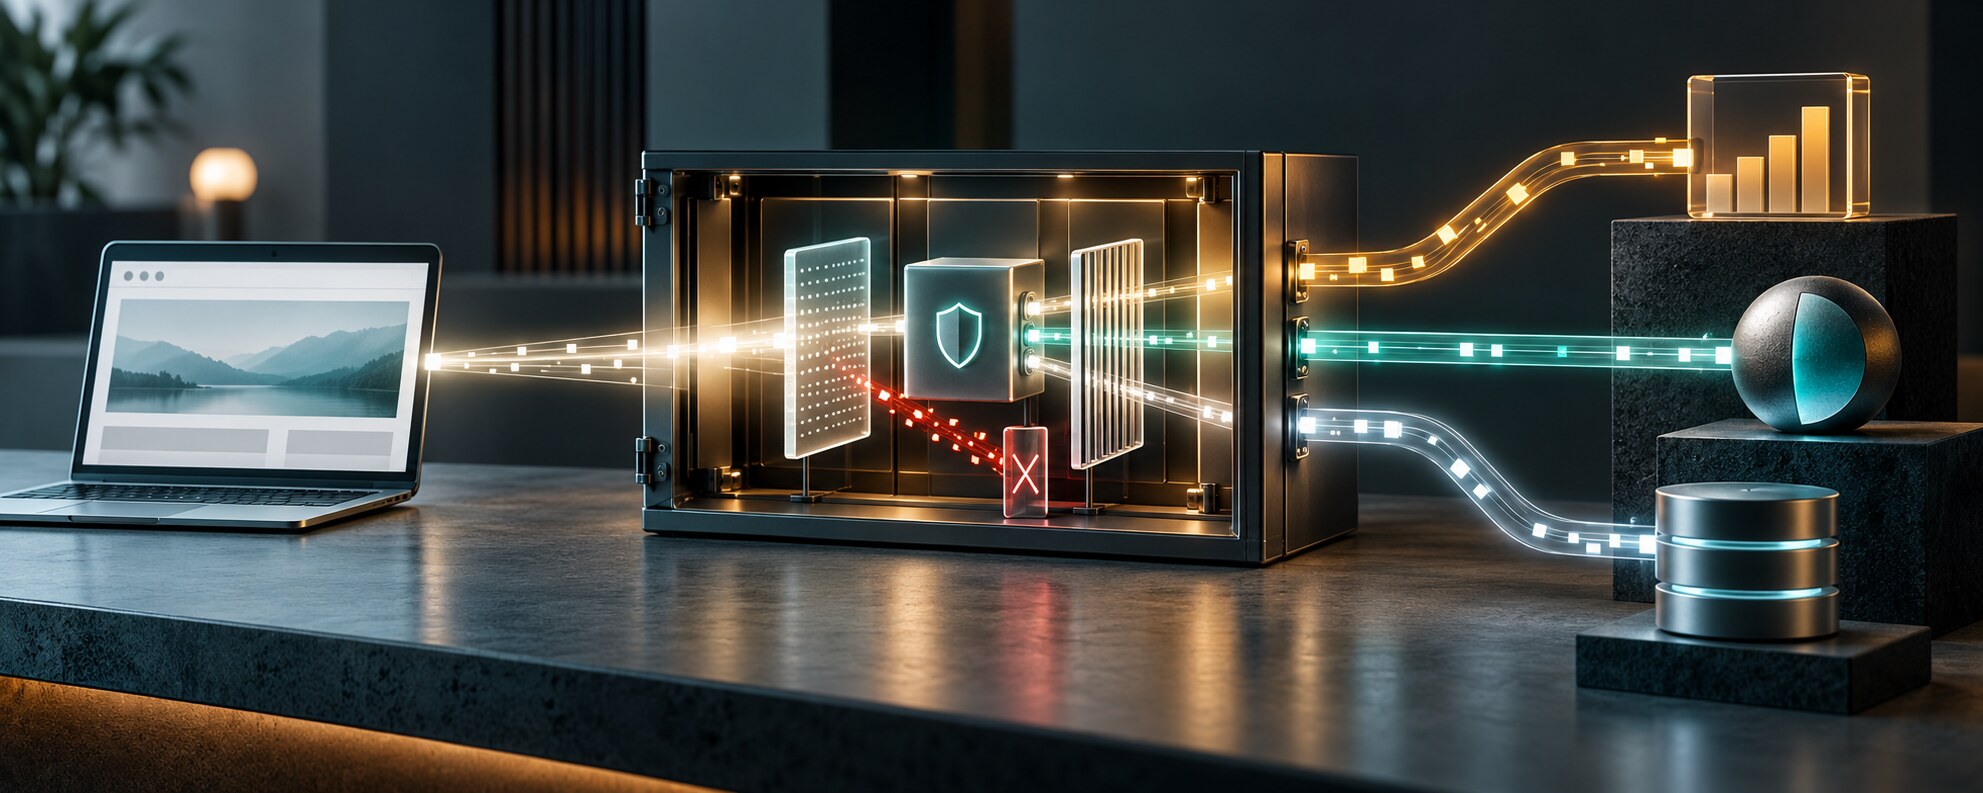
Server-side tagging is often presented as a way to make analytics faster, more private, and more reliable. It can help with all three, but it cannot rescue a measurement plan that sends the wrong event, loses the user or session identifier, ignores consent, or applies incorrect business rules.
The useful question is not whether your organization should move “to the server.” It is which parts of the measurement workflow belong in the browser, which belong in a controlled processing layer, and how you will prove that the resulting data still represents what happened.
What server-side tagging actually changes
In a typical client-side setup, the browser loads a web tag container. When someone views a page or completes an action, the browser sends requests directly to analytics, advertising, or other vendor endpoints. Each vendor may require its own tag, library, request, and set of browser-side rules.
Google Tag Manager’s server-side model adds a second container. The web container still observes activity and sends an HTTP request, but a server container receives that request first. The server container can validate, transform, enrich, or reject the data before dispatching vendor-specific requests. Google describes this as a web container plus a server container running in a cloud environment, with the server container acting as an intermediary endpoint.
That extra layer changes the control point. Instead of every vendor receiving the browser’s raw event directly, your team can decide what the relay is allowed to forward, what fields need to be removed, and which destination should receive each approved event.
What the server layer can improve
Fewer browser-side dependencies. A server-side setup can reduce the amount of vendor code and the number of outbound requests that the browser must execute. That may help page performance, but it is not an automatic Core Web Vitals fix. The web container still has to create a valid event, and the server still has to process it quickly.
More deliberate data distribution. A server container can screen fields before forwarding them. For example, a relay might keep an internal transaction identifier for reconciliation while removing a free-text form response that should never reach an advertising endpoint. This creates a useful boundary between data collected and data distributed.
Centralized routing and transformation. A single approved event can be mapped to different vendor payloads. An internal purchase event might become an ecommerce event for analytics, a conversion event for an advertising platform, and a record update for a warehouse. Keeping those transformations in a controlled layer can be easier to review than maintaining separate browser tags for every destination.
A place for validation. The relay can check event names, required fields, allowed values, consent state, and basic identity rules before a request leaves your environment. Invalid events can be rejected or logged for review instead of quietly polluting every downstream tool.
What server-side tagging cannot fix
It cannot invent a missing identifier. If the browser never sends a stable client identifier, session identifier, order identifier, or CRM record key, the server cannot reliably reconstruct one after the fact. It may generate an ID, but that creates a new identity rather than recovering the one that should have connected the event to the user’s journey.
It cannot define a vague conversion. A server can route an event called form_submit, but it cannot decide whether that event means a valid lead, a spam attempt, a partial submission, or a completed application. Those definitions belong in the measurement plan and the source workflow.
It does not replace consent management. A server endpoint is still part of a data-collection system. Your implementation must carry consent state into the processing rules and destination requests. Moving a tag behind a server does not make collection lawful or make a vendor eligible to receive every field.
It cannot repair bad source data. If a checkout sends the wrong currency, a donation form sends a stale campaign value, or a CRM update arrives after the reporting window, the server may faithfully distribute incorrect information. Better routing is not the same as better source data.
It does not remove operational responsibility. A server container needs hosting, access controls, secrets management, deployment procedures, monitoring, cost review, and an owner for failures. It adds a controlled layer, not a maintenance-free layer.
Keep the browser event and server event connected
A reliable design begins with a clear event contract. For each event, document its name, triggering action, required fields, optional fields, identity fields, consent requirements, destinations, and validation rules.
For a completed checkout, that contract might include:
- One stable transaction identifier from the commerce or payment source.
- A clear event timestamp and currency.
- Validated value and item data.
- The available client or session identifier, handled according to consent.
- A defined rule for whether refunds, cancellations, and test orders are included.
- A destination map that distinguishes analytics, advertising, CRM, and internal reporting needs.
The server layer should preserve the meaning of the approved event while adapting its shape for each destination. If a transformation changes the meaning, that change belongs in documentation and testing, not only in a container configuration that may be difficult to audit later.
Where Measurement Protocol fits
Server-side tagging and the Google Analytics Measurement Protocol are related, but they are not interchangeable. Google states that Measurement Protocol is intended to supplement automatic collection through Google tag, Tag Manager, or Firebase, not replace it. It is useful for server-to-server and offline interactions, such as recording a payment outcome that happens after the browser session has ended.
Measurement Protocol requests also have important limits. A successful HTTP response only proves the request was received. Google’s reference says malformed or incorrectly processed payloads may not return an error code, so teams should use the validation server during testing and reconcile downstream results after sending.
For web events, the request must use the correct measurement ID and client ID. Session-based use cases may require a session ID and an appropriate event timestamp. The API secret must remain private and should never be exposed in client-side code. These details are part of the data contract, not optional implementation polish.
A practical validation workflow
Test the whole path in layers. Start with the browser event and confirm that the expected payload is created under each relevant consent state. Then inspect what the server container receives, what it removes or changes, and what it sends to each destination.
- Test the source action. Use controlled page views, form submissions, checkouts, and rejected scenarios. Include duplicate clicks, refreshes, validation errors, test orders, and incomplete journeys.
- Inspect the relay input. Confirm event names, identifiers, timestamps, values, consent signals, and source metadata. Check that sensitive fields are not being passed unnecessarily.
- Test processing rules. Verify routing, filtering, transformations, deduplication keys, and rejection behavior. Record why a request was blocked.
- Inspect destination requests. Confirm each vendor receives only the fields it needs, with the expected event name and identifier mapping.
- Reconcile outcomes. Compare approved source events with analytics events, advertising conversions, CRM records, and internal reporting. Track rejected, delayed, duplicated, and unmatched records.
- Test failure and recovery. Decide what happens when the server endpoint is unavailable, a destination returns an error, a secret expires, or a schema changes. Add alerts and a retry policy that cannot create duplicate business events.
Google’s server-side tagging guidance explains the architectural distinction and the potential for screening and modifying data before it reaches third parties. The Measurement Protocol documentation explains how server-to-server events supplement tagged collection, while the reference documentation describes validation behavior and payload limits.
Choose the architecture around the risk
Server-side tagging is most useful when an organization has several destinations, meaningful privacy boundaries, a need to control vendor payloads, or events that must be joined with trusted server-side outcomes. It may be unnecessary for a small site with a simple, well-governed measurement plan and few third-party tags.
The decision should account for hosting cost, implementation complexity, consent requirements, identity quality, vendor support, observability, and the team’s ability to maintain the system. A relay that nobody monitors can become another place for silent data loss.
DigitalWerks can review the full measurement path, from browser events and consent states through server-side processing, vendor requests, CRM outcomes, and reporting reconciliation. The goal is not simply to move tags behind a server. It is to make the data flow understandable, testable, and fit for the decisions your organization needs to make.